Professional teams managing client relationships, projects, and service delivery face a critical challenge: maintaining accurate, accessible, and secure customer data across multiple touchpoints. Database management CRM represents the foundation of modern customer relationship systems, transforming scattered information into actionable intelligence. For businesses operating project management platforms, service desks, or professional services automation tools, understanding how to architect, secure, and optimise CRM databases determines whether teams gain competitive advantage or drown in data chaos. This comprehensive guide explores the technical and strategic dimensions of database management CRM, equipping decision-makers with frameworks to build resilient, scalable customer data infrastructure.
Understanding Database Management CRM Architecture
Database management CRM encompasses the structural design, storage patterns, and data governance policies that enable customer relationship platforms to function reliably at scale. The architecture you choose directly impacts system performance, data integrity, and your team’s ability to extract meaningful insights from customer interactions.
Relational vs Non-Relational Database Approaches
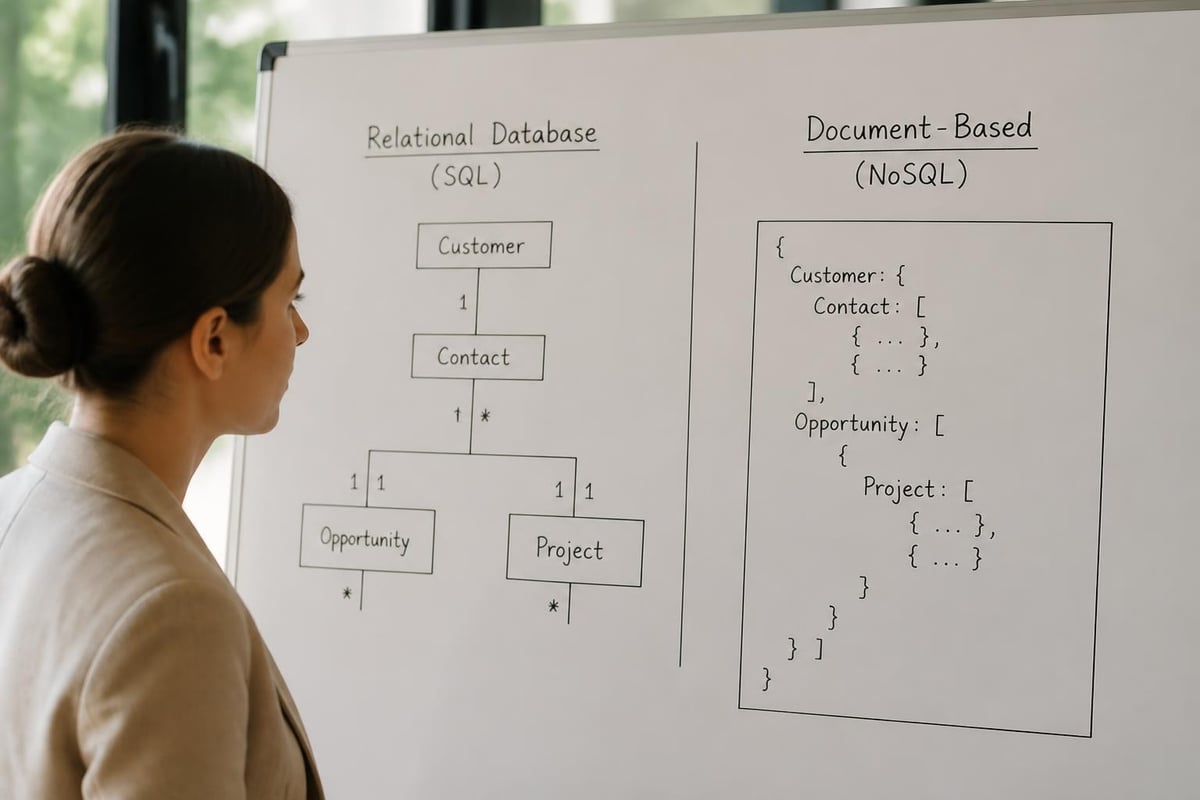
Traditional CRM systems predominantly rely on relational databases (PostgreSQL, MySQL, SQL Server) to enforce data consistency through normalised schemas and foreign key relationships. This approach excels when managing structured customer records, contact hierarchies, opportunity pipelines, and transactional histories where referential integrity matters.
Key advantages of relational database management CRM:
- ACID compliance ensures data consistency across concurrent operations
- Mature query optimisation for complex joins and aggregations
- Robust indexing strategies for fast customer lookups
- Strong support for transaction rollback and point-in-time recovery
Non-relational databases (MongoDB, Cassandra, DynamoDB) suit scenarios where schema flexibility outweighs strict consistency requirements. Marketing automation platforms often combine both approaches, using relational databases for core CRM entities whilst leveraging NoSQL stores for high-velocity event tracking and personalisation data.
For professional services automation platforms managing both client relationships and project delivery, hybrid architectures increasingly dominate. Customer master records reside in relational tables whilst project activity streams, time entries, and collaboration logs flow into document stores optimised for append-heavy workloads.
Multi-Tenancy Patterns for SaaS CRM Platforms
Modern database management CRM must accommodate multi-tenancy, where a single application instance serves multiple customers whilst maintaining strict data isolation. Microsoft’s guidance on multitenant solutions outlines three primary patterns with distinct trade-offs.
| Tenancy Model | Isolation Method | Scalability | Cost Efficiency | Complexity |
|---|---|---|---|---|
| Database per tenant | Separate database instances | High | Low | Low |
| Schema per tenant | Shared database, separate schemas | Medium | Medium | Medium |
| Shared schema | Row-level tenant ID filtering | Low | High | High |
The shared schema approach maximises resource utilisation but requires meticulous query filtering to prevent data leakage between tenants. Every query must include tenant identifiers in WHERE clauses, necessitating comprehensive row-level security policies.
Database-per-tenant models simplify compliance and enable granular performance tuning per customer, yet managing thousands of database instances introduces operational overhead. Schema-per-tenant strikes a middle ground, particularly suited for B2B platforms serving mid-market enterprises.
Optimising Database Performance for CRM Workloads
CRM systems exhibit distinctive query patterns: frequent small reads (contact lookups, opportunity details), periodic bulk updates (data enrichment, deduplication), and analytical aggregations (pipeline forecasting, activity reports). Database management CRM performance optimisation demands understanding these workload characteristics.
Strategic Indexing for Customer Data Access
The PostgreSQL CREATE INDEX documentation details various index types, each suited to specific CRM query patterns. B-tree indexes accelerate equality and range queries on customer IDs, email addresses, and date fields.
Critical indexes for database management CRM systems:
- Unique index on customer email/external ID for deduplication
- Composite index on (tenant_id, customer_id) for multi-tenant queries
- Partial index on active opportunities with recent activity
- GIN index on JSONB fields storing custom CRM properties
- Full-text search index on contact notes and communication history
Covering indexes that include all columns referenced in SELECT clauses eliminate table lookups entirely, dramatically improving response times for common customer detail queries. However, each index imposes write overhead and storage costs, requiring deliberate choices about which access patterns merit indexing.
Query execution plans reveal whether indexes are utilised effectively. In PostgreSQL, EXPLAIN ANALYZE exposes sequential scans indicating missing indexes or statistics requiring refresh. For business management systems handling thousands of daily customer interactions, query plan analysis should be routine operational practice.
Horizontal Partitioning Strategies
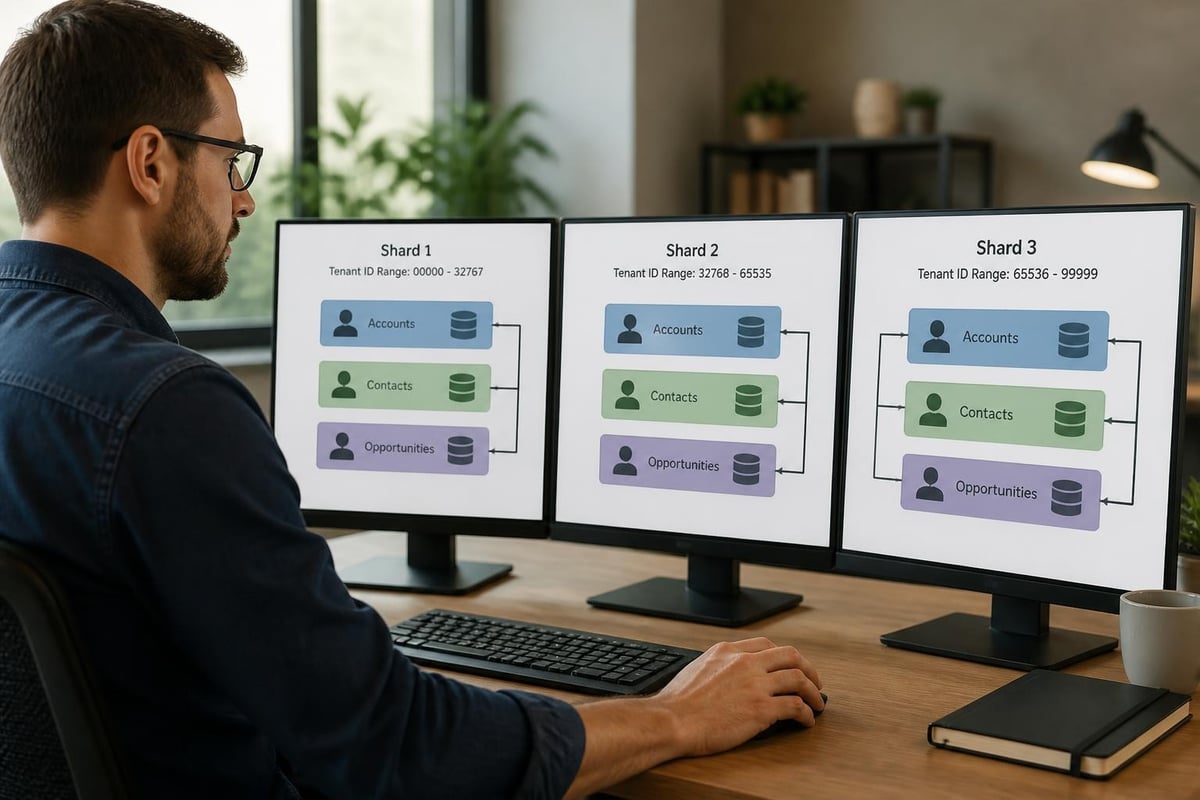
As CRM databases grow beyond tens of millions of records, horizontal partitioning (sharding) becomes necessary to maintain query performance. The Azure sharding pattern describes partitioning by customer ID, geography, or time period to distribute data across multiple database instances.
Time-based partitioning suits audit trails, communication logs, and activity histories where queries predominantly target recent data. Partitioning by tenant ID aligns naturally with multi-tenant architectures, enabling complete tenant isolation at the physical storage level.
Shard key selection criteria:
- High cardinality to distribute data evenly across shards
- Aligned with dominant query patterns to minimise cross-shard queries
- Immutable after record creation to avoid expensive re-sharding
- Balanced write distribution to prevent hot partition bottlenecks
Cross-shard queries for global reports require aggregation logic in the application layer or a separate analytics data warehouse. Modern database management CRM platforms increasingly adopt lambda architectures, serving operational queries from sharded transactional databases whilst directing analytical workloads to columnar stores like Snowflake or BigQuery.
Security and Compliance in CRM Database Management
Customer data represents both competitive asset and regulatory liability. Database management CRM security encompasses encryption, access controls, audit logging, and compliance with data protection regulations including GDPR, CCPA, and industry-specific frameworks.
Encryption at Rest and in Transit
All CRM databases must implement transparent data encryption (TDE) for data at rest and TLS 1.3 for data in transit. Database-level encryption protects against storage media theft but leaves data vulnerable during query processing.
For highly sensitive customer information, column-level encryption using application-managed keys provides defence-in-depth. Only authorised application components possessing decryption keys can access plaintext data, even if database credentials are compromised.
The NIST publications repository provides authoritative guidance on cryptographic key management, secure key rotation schedules, and separation of duties for encryption key administrators. Implementing these standards demonstrates due diligence in protecting customer data.
Role-Based Access Control and Audit Trails
Database management CRM systems require granular permission models reflecting organisational roles and data sensitivity. Sales representatives access customers within their territories, managers view team-wide pipelines, whilst executives access aggregate reporting across the entire customer base.
Row-level security policies enforce these boundaries at the database layer, preventing privilege escalation through SQL injection or compromised application credentials. PostgreSQL’s row security policies and SQL Server’s row-level security feature enable declarative access rules based on session context.
Comprehensive audit logging captures all data access and modification events, essential for compliance investigations and security incident response. Logs should record user identity, timestamp, affected records, and query details, streamed to immutable append-only storage for tamper-evident audit trails.
For platforms managing service desk support alongside CRM functionality, unified audit trails across customer records and support tickets provide complete visibility into customer interaction history.
Backup, Recovery and Business Continuity
Database failures threaten business continuity and customer trust. Robust database management CRM includes automated backup strategies, tested recovery procedures, and disaster recovery planning aligned with business requirements for data loss tolerance and recovery time.
Recovery Point and Recovery Time Objectives
Recovery Point Objective (RPO) defines maximum acceptable data loss measured in time, whilst Recovery Time Objective (RTO) specifies maximum tolerable downtime before normal operations resume. AWS disaster recovery guidance maps these objectives to technical implementation patterns.
| DR Strategy | Typical RTO | Typical RPO | Relative Cost | Use Case |
|---|---|---|---|---|
| Backup and restore | 12-24 hours | 1-24 hours | Low | Development, testing |
| Pilot light | 1-4 hours | Minutes | Medium | Non-critical production |
| Warm standby | Minutes | Seconds | High | Business-critical CRM |
| Multi-site active/active | Near-zero | Near-zero | Very high | Global CRM platforms |
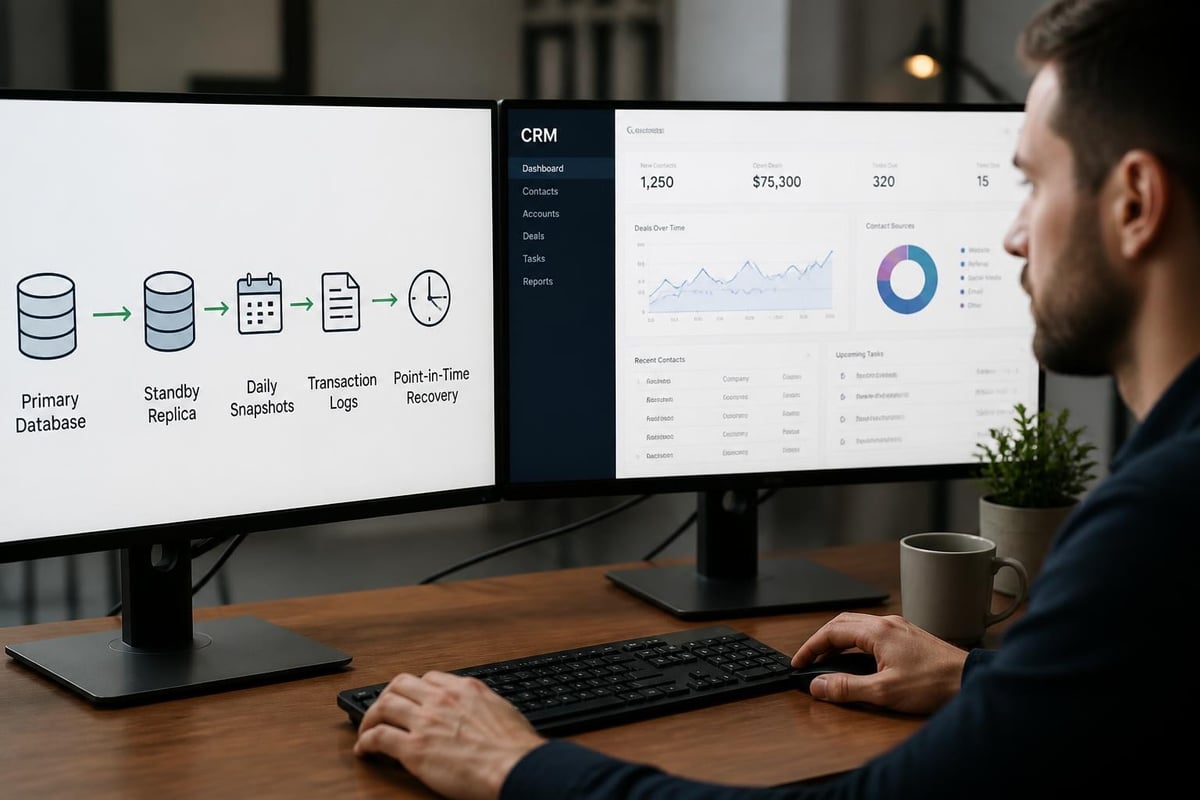
Continuous replication to standby replicas minimises RPO but incurs infrastructure costs for maintaining synchronised database instances. Point-in-time recovery from transaction logs balances cost and recovery granularity for most business scenarios.
Automated Backup Testing and Validation
Untested backups offer false confidence. Database management CRM best practices mandate regular restore drills to production-equivalent environments, validating both backup integrity and recovery procedures.
Automated backup validation scripts should verify file checksums, attempt restore to temporary instances, run schema consistency checks, and confirm row counts match source databases. These validations catch corrupt backups, incomplete snapshots, and configuration drift before disasters occur.
For software development teams managing client projects through CRM-integrated platforms, backup strategies must encompass both customer data and project artefacts, ensuring complete recovery capability following system failures.
Integration Patterns and Data Synchronisation
Modern database management CRM rarely operates in isolation. Customer data flows between marketing automation platforms, billing systems, support ticketing tools, and analytics warehouses, creating complex integration landscapes requiring careful orchestration.
ETL vs Streaming Synchronisation
Traditional Extract-Transform-Load (ETL) processes run batch synchronisation on scheduled intervals, acceptable when hourly or daily data freshness suffices. Customer activity dashboards, pipeline forecasts, and monthly reporting typically tolerate batch latency.
Event-driven streaming synchronisation using change data capture (CDC) propagates database changes in near-real-time to downstream systems. This approach suits scenarios where immediate consistency matters: updating customer support agents when opportunities close, triggering onboarding workflows when deals are won, or updating billing systems when subscription tiers change.
Database triggers and transaction log mining provide CDC mechanisms at different architectural layers. Triggers execute synchronously within transactions, guaranteeing consistency but impacting write throughput. Log mining operates asynchronously, minimising transactional overhead whilst introducing eventual consistency windows.
API-First Data Access and Microservices
As organisations decompose monolithic CRM systems into microservices, database-per-service patterns prevent direct database access across service boundaries. Each microservice exposes well-defined APIs for data access whilst maintaining autonomy over its database schema.
This architectural shift complicates reporting and analytics requiring data from multiple services. Solutions include API-based federation, dedicated reporting databases populated via ETL, or event sourcing patterns where services publish domain events to central event streams consumed by analytics platforms.
The Customer Data Platform Institute research explores how CDPs complement traditional CRM systems by unifying customer data from disparate sources into persistent, analytics-ready profiles. Understanding when specialised CDPs add value versus expanding CRM database capabilities guides integration architecture decisions.
Operational Excellence and Monitoring
Production database management CRM demands continuous monitoring, proactive performance tuning, and systematic capacity planning to maintain service levels as customer data volumes and query complexity grow.
Key Performance Indicators for CRM Databases
Essential database health metrics:
- Query response time percentiles (p50, p95, p99)
- Transaction throughput and error rates
- Connection pool utilisation and wait events
- Cache hit ratios and buffer pool efficiency
- Replication lag for standby replicas
- Disk I/O utilisation and queue depths
Establishing baselines during normal operations enables anomaly detection alerting when metrics deviate significantly. Sudden spikes in slow query counts indicate missing indexes or query plan regressions requiring immediate investigation.
For platforms combining CRM with SLA management capabilities, database performance directly impacts contractual service level commitments. Query timeouts during peak hours translate to missed SLA targets and customer dissatisfaction.
Capacity Planning and Growth Projections
Database capacity planning balances current performance against projected growth trajectories. Analysing historical trends in customer record creation, interaction volumes, and data retention requirements informs infrastructure scaling decisions.
Leading indicators include monthly active customer growth rates, average attachments per customer record, and API call volumes. Extrapolating these trends with seasonal adjustment factors produces capacity requirement forecasts for database compute, storage, and network resources.
Cloud-native databases offer vertical and horizontal scaling options responding to capacity demands. Vertical scaling (larger instance types) suits short-term growth whilst horizontal scaling (sharding, read replicas) addresses long-term architectural scalability.
Data Quality and Governance Frameworks
Database management CRM extends beyond technical infrastructure to encompass data quality policies, governance frameworks, and organisational processes ensuring customer data remains accurate, complete, and actionable.
Deduplication and Master Data Management
Customer records accumulate duplicates through multiple entry points: web forms, sales imports, marketing campaigns, and manual data entry. Duplicate detection algorithms compare records across name variations, email addresses, phone numbers, and company identifiers, consolidating matches into golden records.
Probabilistic matching assigns similarity scores based on fuzzy string matching and phonetic algorithms, flagging potential duplicates for manual review. Deterministic rules enforce exact match criteria on unique identifiers, automatically merging records meeting threshold confidence levels.
Data quality dimensions for CRM databases:
- Completeness: Percentage of required fields populated
- Accuracy: Validation against authoritative sources (email verification, address standardisation)
- Consistency: Cross-field validation rules (country matches postal code format)
- Timeliness: Recency of last update or verification
- Uniqueness: Absence of duplicate records
Master data management platforms centralise customer data governance, establishing workflows for data stewardship, quality scoring, and continuous enrichment. These capabilities prove essential for enterprises managing customer relationships across multiple business units and geographies.
Privacy Controls and Data Retention Policies
GDPR right to erasure, CCPA deletion requests, and industry-specific retention requirements mandate systematic data lifecycle management. Database management CRM must support soft deletes preserving referential integrity whilst marking records for purging, scheduled hard deletion after grace periods, and anonymisation for historical analytics.
Implementing privacy-by-design principles during schema design simplifies compliance. Separating personally identifiable information into dedicated tables with foreign key relationships enables surgical deletion whilst preserving anonymised transaction histories for business analytics.
Data retention policies balance legal compliance, operational needs, and storage costs. Archiving aged customer interactions to cold storage reduces active database footprint whilst maintaining accessibility for occasional retrieval, implementing tiered storage strategies aligned with data access patterns.
Emerging Trends in Database Management CRM
Technology evolution continuously reshapes database management CRM capabilities. Understanding emerging trends enables strategic platform decisions positioned for future requirements rather than solely addressing current constraints.
Machine Learning Integration for Predictive CRM
Modern CRM platforms embed machine learning models predicting customer churn probability, next-best-action recommendations, and opportunity win likelihood. Training these models requires access to historical customer interaction patterns, necessitating efficient bulk data extraction from operational databases.
Feature stores bridge operational and analytical databases, materialising ML features from raw CRM data whilst maintaining consistency between training and inference data. This architecture prevents training-serving skew degrading model accuracy in production.
Vector databases supporting similarity search enable semantic customer record matching, duplicate detection based on meaning rather than string similarity, and recommendation engines suggesting relevant content based on customer behaviour patterns.
Distributed SQL and Global CRM Deployments
Organisations operating across continents require low-latency customer data access from geographically dispersed teams. Distributed SQL databases (CockroachDB, YugabyteDB) provide ACID guarantees whilst replicating data across regions, enabling local reads and coordinated distributed writes.
These systems suit global CRM deployments where European sales teams access customer records stored primarily in EU data centres whilst maintaining consistency with regional replicas in Asia-Pacific and Americas. Data sovereignty requirements often mandate customer data residency within specific jurisdictions, necessitating geo-partitioning capabilities.
The operational complexity of distributed databases requires expertise in consensus protocols, partition management, and distributed transaction troubleshooting. Organisations must weigh global consistency benefits against operational overhead and vendor ecosystem maturity.
Real-Time Analytics and Operational BI
Traditional separation between operational CRM databases and analytical data warehouses introduces latency in reporting current customer states. Hybrid transactional/analytical processing (HTAP) databases enable real-time analytics directly against operational data without ETL delays.
Columnar storage engines co-located with row-based transactional storage support both OLTP and OLAP workloads within unified databases. Sales dashboards reflect current pipeline states without waiting for nightly ETL runs, enabling agile decision-making based on fresh customer intelligence.
Platforms addressing reporting challenges increasingly demand this architecture, as teams expect instant visibility into customer interactions, project status, and resource utilisation without reconciling data across disconnected systems.
Effective database management CRM transforms customer data from administrative burden into strategic asset, enabling teams to deliver exceptional client experiences whilst maintaining operational efficiency and regulatory compliance. Chronodesk provides comprehensive work platform capabilities integrating project management, CRM, and professional services automation on a unified database architecture, eliminating data silos whilst delivering the scalability, security, and performance professional teams demand. Explore how Chronodesk’s structured approach to customer and project data management can elevate your team’s delivery capabilities and client relationships.